


DevOps consulting and cloud services for AWS, DigitalOcean and Kubernetes.
Automated deploys, monitoring and security, so releases are routine.
Content reviewed
What a DevOps consulting engagement covers
We take over a running system in small steps you can undo: first automated builds and deploys, then monitoring and alerts, then security and backups. Releases become routine, not a late-night event. We run FeelEat on DigitalOcean with Kubernetes and Docker, and LeadTrack AI on AWS with Docker.
Infrastructure only gets noticed when it fails — at peak traffic, during the demo, at 3 a.m. The usual causes are never exotic: hand-edited servers, deploys that depend on one person, alerts nobody reads, and costs nobody owns.
We make it boring on purpose. Everything as code, every deploy automated and reversible, every system observable before it misbehaves. We built the full DevOps for FeelEat on DigitalOcean, with Kubernetes and Docker, and for LeadTrack AI on AWS, with Docker.
Engineered for quiet.
The six layers of a production cloud that lets everyone sleep.
Cloud architecture
Right-sized, multi-environment set-ups on AWS or DigitalOcean, designed around the load you actually have.
CI / CD
Pipelines that test, build and ship on every merge — with staged rollouts and one-click rollback.
Security & monitoring
Least-privilege IAM, secrets management, audit trails and alerts tuned to wake humans only when humans help.
Infrastructure as Code
Terraform for every resource — reviewable, reproducible, and rebuildable from scratch in an afternoon.
Auto-scaling & cost control
Capacity that follows demand and budgets with owners — performance and the bill both under control.
Incident response
Runbooks, automated alerts around the clock and blameless post-mortems — with an on-call rota available on a managed DevOps retainer.
Stabilise, automate, forget.
We take over running systems in small, reversible steps, and your users never notice the handover.
01Audit & map
Every resource, dependency and single point of failure documented — including the ones only one engineer knew about.
02Codify the truth
Existing infrastructure imported into Terraform. From here, every change lands through a reviewed pull request instead of an SSH session.
03Automate delivery
CI/CD with tests, staging and rollback. Deploys go from feared events to non-events, daily.
04Observe & harden
Dashboards, alerting, load tests and security review — then optional ongoing operation by the same team.
Your product could be the next case on this page.
Start with a free 4-hour workshopKubernetes under a food-tech operation.
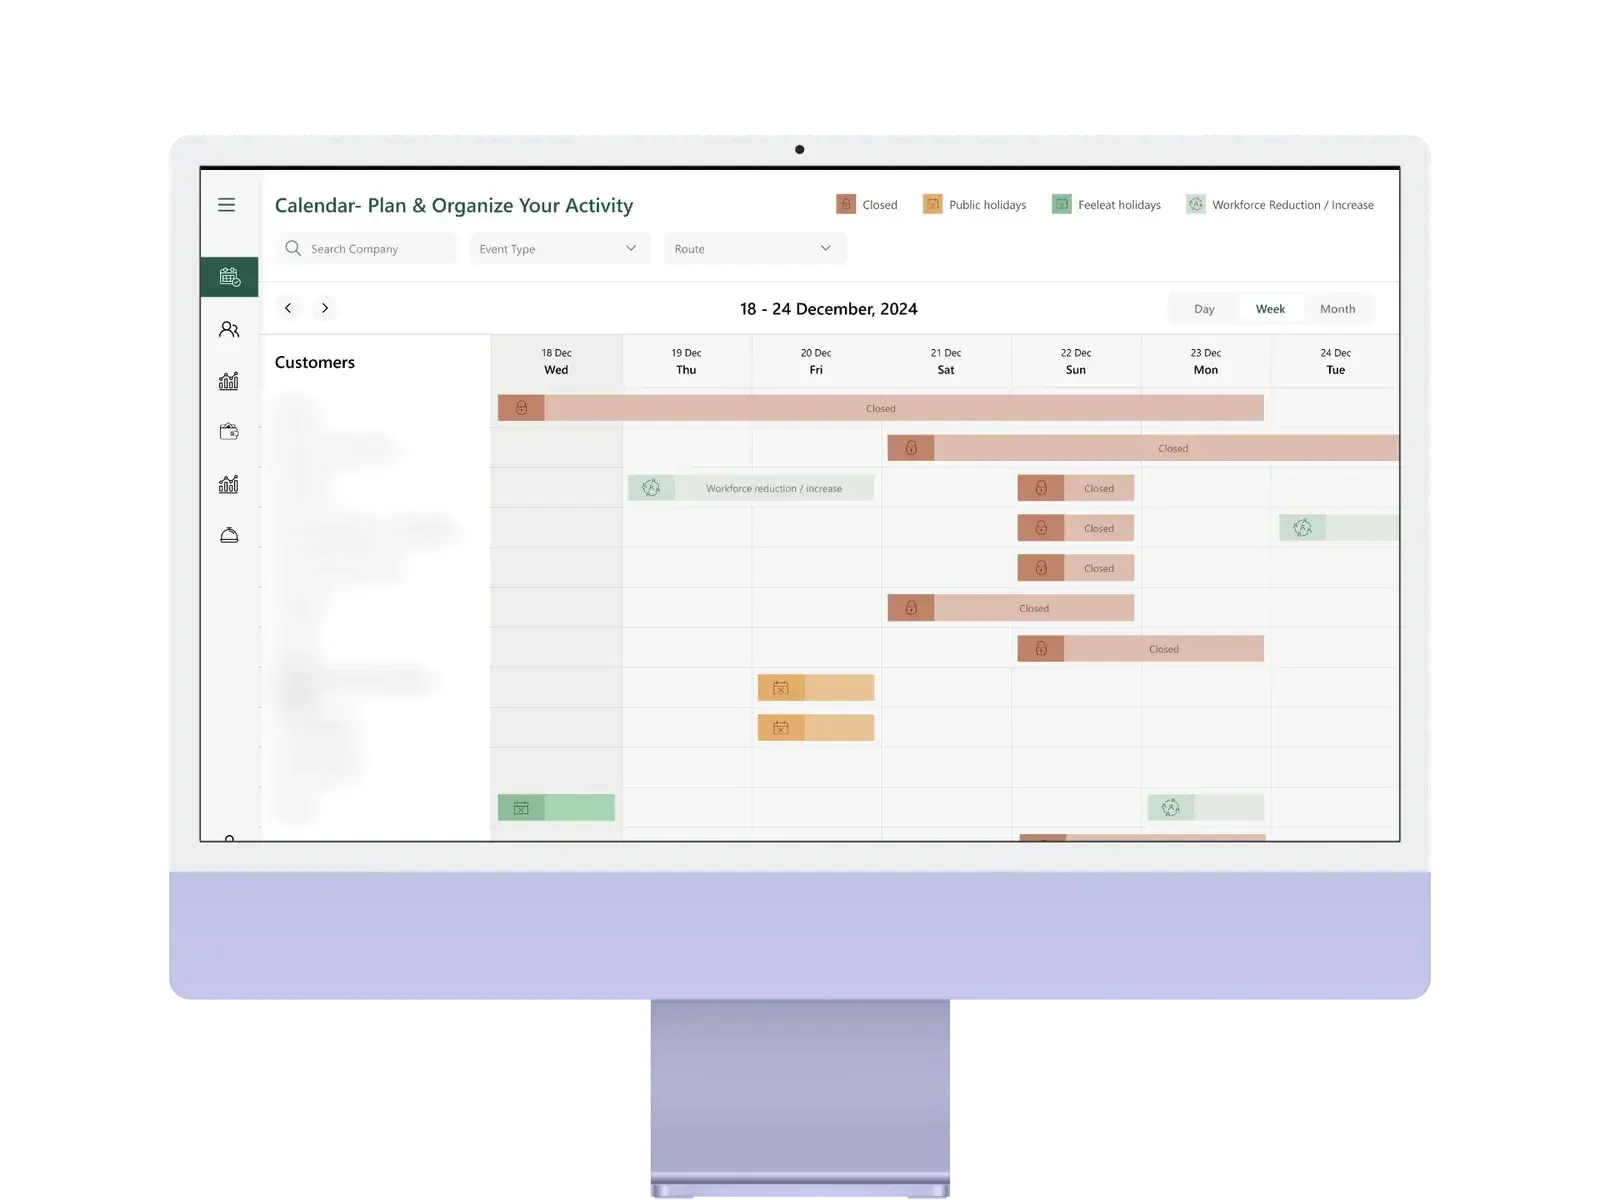
The full DevOps behind FeelEat's software, on DigitalOcean. For LeadTrack AI we did the same on AWS.
FeelEat
We built FeelEat's DevOps on DigitalOcean: services packaged in Docker containers and run on Kubernetes. LeadTrack AI runs on AWS, also in Docker, with DevOps by the same team.
Terraform and company.
AWS or DigitalOcean, Docker and Kubernetes, with everything automated: the toolchain your next hire already knows.
What runs on these foundations.
Most of our infrastructure engagements exist to carry one of these.
The on-call answers.
Takeovers, bills, Kubernetes, compliance — all answered by the engineers who run these systems.
Put it in a brief. A senior engineer reads it and replies within one business day.
Can you take over infrastructure we already run?
Yes — that is the most common engagement. We audit, import everything into Terraform, and stabilise before changing anything. No big-bang migration; your uptime is never the gamble.
Will this reduce our cloud bill?
Often, through right-sizing, scheduling and cleaning up storage, but we only name a figure after the audit. More importantly, costs become visible and owned, so the bill stops being a monthly surprise.
Do we still need our own DevOps hire?
Not necessarily. We can run the operation for you, or build the platform and train your own hire into it. Either way you own the code and the cloud accounts, so there is no lock-in.
How do you handle compliance — GDPR or ISO?
Infrastructure as code turns compliance evidence into a by-product: audit trails, access reviews and reports are generated automatically.
Do we need Kubernetes?
Probably not. Most teams under 50 engineers are better served by managed PaaS (Vercel, Fly, Railway, ECS, Cloud Run). We adopt Kubernetes when its operational complexity is justified by genuine scale or compliance requirements.
What about disaster recovery?
We design RTO/RPO targets to match what the business actually needs, implement automated backups with tested restore procedures, and can run regular restore drills when your compliance rules ask for them.
What does good observability actually look like?
The three pillars done deliberately: structured logs, metrics, and distributed traces correlated by a request ID, with OpenTelemetry as the instrumentation layer so you're not locked to one vendor. The test is whether an on-call engineer can go from an alert to the root cause in minutes without SSHing into a box. If a dashboard never gets opened, it does not count.
How do you make deploys safe enough to do multiple times a day?
Trunk-based development, automated tests as the merge gate, and progressive delivery — canary or blue-green with automatic rollback on error-rate or latency regression. Feature flags decouple deploy from release so shipping code and turning it on are separate decisions. Frequent small deploys are safer than rare big ones, which is the opposite of most teams' intuition.
When did you last deploy
without holding your breath?
Tell us about your stack, your deploy day and your last incident. A senior infrastructure engineer replies within one business day with what we would stabilise first.